

Executive Summary
Your company has spent years building institutional knowledge, but as companies increasingly leverage AI tools, most of this critical knowledge is overlooked at integration—at high cost to your business.
Your institutional knowledge exists in many places: product manuals, support playbooks, compliance policies, contract archives. What is missing is the connection between it and the AI your teams already use. Retrieval-augmented generation, or RAG, is how that connection gets made—but getting it right goes beyond simply choosing a model.
Model choice doesn’t make internal AI tools more successful. Internal context does.
You may not need a new corpus (knowledge base), but what exists still needs cleaning, permissions, and connection.
Grounding makes answers checkable. It does not guarantee correctness.
The same question can have two correct answers. Who is asking the question matters.
The Problem Nobody Raises In The AI Budget Meeting
Your company is likely already investing in AI: copilots, chatbots, generative tools. The budgets are real, and the expectations are high. But a failure pattern keeps showing up—because AI tools know a great deal about the world and nothing about your business.
Ask a generic assistant about your refund policy: it will not know. Ask about the terms in a contract signed last quarter: it will guess. Ask it to explain your escalation process to a new hire: it will produce a textbook answer that has nothing to do with how your organization actually works.
AI tools have a lot of potential, but when internal applications of AI fail, it is usually not a model failure; it is a connection and governance failure. When this happens, manual work creeps back in, and failures pile up: a support agent checks three systems for one ticket, a rep quotes a price from a sheet that was superseded eighteen months ago, or a compliance officer reads a long regulatory document by hand because the AI doesn’t have access to it or any of the organizational context to understand it.
Here is what almost nobody tells you about AI: most stalled projects fall apart in the layers around the model rather than in the choice of model.
Success with AI depends on three questions:
- Is the content good?
- Can the right passage be found?
- Does anyone own keeping the content true?
Get those wrong, and the strongest model on the market will still produce answers your teams will stop trusting.
What RAG Is
Retrieval-augmented generation (RAG) was introduced in a 2020 NeurIPS paper by Patrick Lewis and colleagues at Facebook AI Research, Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks (Advances in Neural Information Processing Systems 33, pp. 9459 to 9474). The idea is that instead of expecting a language model to have memorized everything, you retrieve the relevant material when a question is asked and give the model that material to answer from.
When someone asks a question, the RAG searches your own content, pulls the passages most likely to contain the answer, and the model answers from those, with the source attached. RAG simply connects the system to your content at the point of the question.
What RAG is not: retraining the model. Retraining alters the model itself and is a far larger undertaking in cost and time.
01
Content goes in
Your documents are processed and indexed, then kept in sync as they change.
02
The passage is found
A question retrieves the specific sections most likely to answer it, not whole documents.
03
The answer is grounded
The model answers from what was retrieved and links back to it.
Three stages. Retrieval determines what the model sees.
Your Knowledge Base Is Already An Asset
You will rarely need to create a new body of knowledge. All the “corpus” your AI needs is already in operational documents, product documentation, support history, contracts, competitive research, and meeting archives. You likely have years of it, already written.
What you will usually need to do is clean and classify the content you already have, protect it with permissions, and connect it to your AI tools. That work is real, and it varies enormously between organizations. A knowledge base with a clear owner and current documents may need little work to become actionable; a knowledge base that has accumulated for a decade across four systems with no retirement policy will need a lot. The latter will require more up-front time investment to ensure you have one version of truth (not many) and that it’s current and accurate.
Which of those you are dealing with is the first thing to establish, which is why it is the first thing we look at in our enterprise knowledge and RAG work.
What Connected Knowledge Changes For Your Teams
A connected knowledge ecosystem lets support agents get the current policy clause with a reference from one interface, instead of navigating several systems and hoping the version it accessed is right. It ensures that sales reps prepare from approved documentation rather than memory. It ensures that new hires ask the system how something is handled here and get your actual process, which takes a recurring load off senior staff. And for compliance teams, it lets them query thousands of pages conversationally and get cited answers, turning a tedious reading task into a rapid search task.
Those are the outcomes a well-implemented system makes possible.
| Function | Common starting point | Target outcome with a well-implemented system |
|---|---|---|
| Support | Agents search multiple systems per ticket | One interface, cited answer, resolved on first contact more often |
| Sales | Reps prepare from memory or stale material | Current, approved answers before the call |
| Onboarding | New hires depend on senior colleagues for process | Self-service answers from real process, from the first week |
| Compliance | Manual reading to locate a clause | Conversational query with the source attached |
| Leadership | Analyst time spent aggregating by hand | Synthesis across the knowledge base on demand |
The Three Critical Questions That Make These Projects Fail
As we outlined at the start of this article, three factors separate systems that hold up from those that fade after the pilot.
1. Is the Content Good?
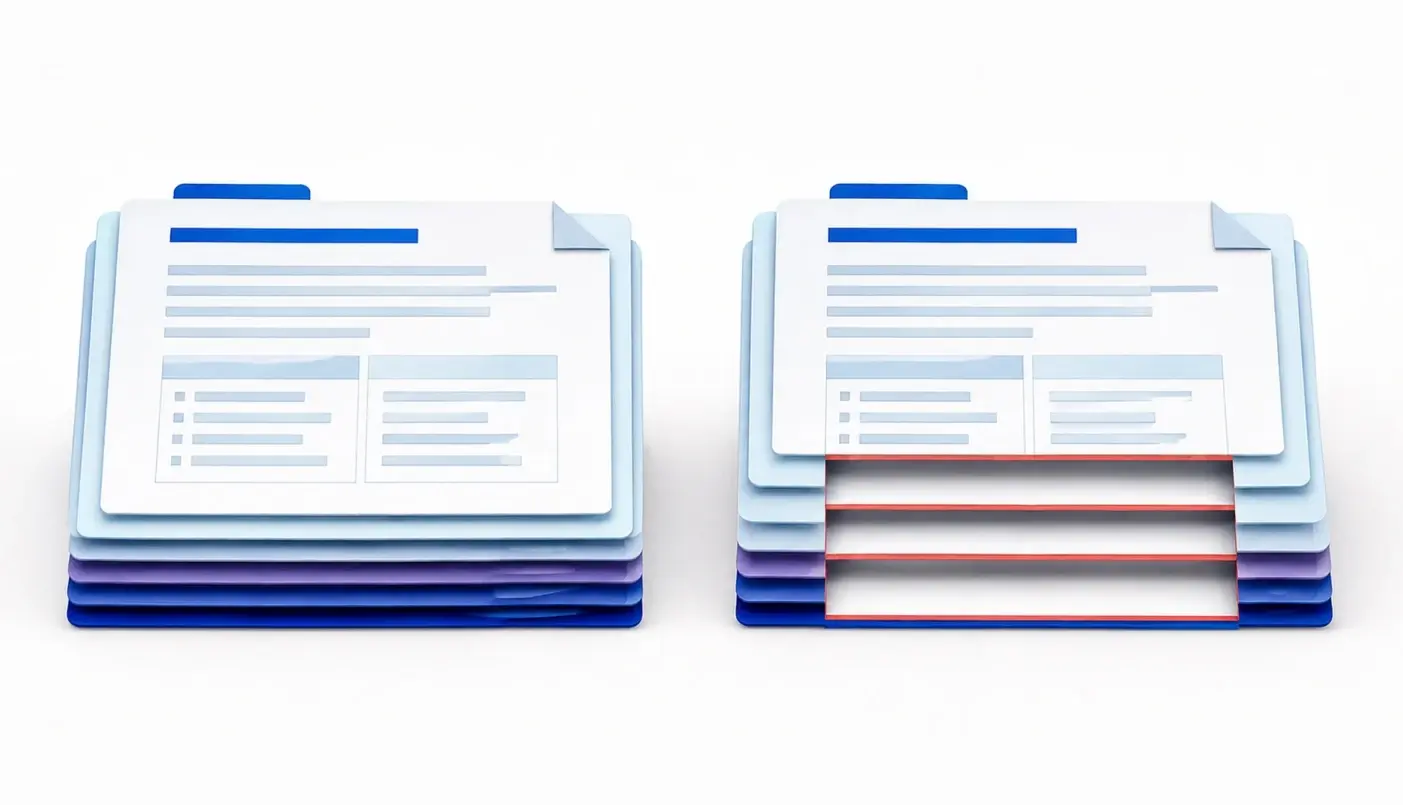
Stale files, duplicate versions, and contradictory policies produce unreliable answers regardless of the model. The typical case is two versions of the same leave policy, one on the HR drive and one on the wiki, giving different notice periods; the assistant answers from whichever version ranks higher for that query, and each answer carries a legitimate-looking citation.
Content quality comes first because the system is only as good as what it retrieves from. Implementation starts with a content review: what belongs in the knowledge base, what needs updating, what should be retired. That is a governance question with a business owner, not an engineering decision.
2. Can the Passage Be Found?
Broad retrieval brings in noise. Chunking, metadata, re-ranking, and grounding are what make an answer precise.
Retrieval precision decides whether anyone keeps using the system. If retrieval is loose or the answer drifts, teams go back to asking a colleague. Nobody files a ticket saying they have stopped trusting the assistant. Adoption just falls.
3. Does Anyone Keep the Content True?
Without a named owner and a review cadence, the knowledge base drifts and the AI answers drift with it. Enterprise knowledge management has always been more of a governance problem than a technology one. Connecting AI to it does not change that, and arguably raises the stakes, because the drift now reaches everyone who asks a question rather than only the person who opened the wrong folder.
What this means for your business: answering these questions before you commit a budget to AI is cheaper than discovering them in month four.
Permission-Aware Retrieval: Should This Person Receive the Answer?
Content, retrieval, and ownership decide whether the answer is right. A fourth question decides whether it is safe to give. Unfortunately, data access rights are often the last question to be considered.
Access rules are not guaranteed to survive ingestion into AI tools. Some enterprise connectors propagate source permissions into the index and some implementations re-check authorization at query time, but neither happens by accident. Where nothing has been built for it, the passage sitting in the index carries no memory that its source file was restricted to the compensation committee. Ask a question that matches its content, and it comes back ranked, summarized, and cited for anyone.
When a well-formed, correctly cited answer arrives in front of someone who was never cleared to receive it, the only way you find out is if that person mentions it.
The question a knowledge system has to answer is not “what does the documentation say.” It is “what does the documentation say, to this person.” Only the second one is safe to deploy.
Making the second query possible means carrying the user’s identity into retrieval. Either the source permissions are propagated into the index, or they are re-checked at query time, and unauthorized content is excluded before it reaches the model. Access changes and deletions then have to reach the retrieval layer quickly. Otherwise, the index quietly becomes a second (and less governed) copy of the source system.
Same query, same index, same moment
“What is our policy on early contract termination?”
Asked by: regional sales manager
Standard terms, termination clauseOwner: Legal. Current version, open to all staff.
Sales handbook, cancellationsOwner: Sales Ops. Current version, open to all staff.
Negotiated amendment, named accountExcluded. Account team only.
Standard terms, earlier versionExcluded. Superseded version.
Termination risk memoExcluded. Legal privilege.
Answer: the standard notice period, cited to the termination clause.
Asked by: director for that account
Standard terms, termination clauseOwner: Legal. Current version, open to all staff.
Sales handbook, cancellationsOwner: Sales Ops. Current version, open to all staff.
Negotiated amendment, named accountOwner: Legal. Current version, account team only.
Standard terms, earlier versionExcluded. Superseded version.
Termination risk memoExcluded. Legal privilege.
Answer: the shorter period in the account amendment, cited, and flagged as overriding the standard clause.
Two of those exclusions are access decisions, and two are currency decisions, and all four are enforced at the same point for the same reason.
When Two Approved Documents Disagree
The content section above describes a common case: two versions of a leave policy giving different notice periods. The challenge occurs when both documents are current, both are approved, and they still conflict—because they come from different authorities.
To avoid these kinds of messes in data retrieval, an organization has to define its own hierarchy, and it should be risk-based rather than recency-based. The order varies by use case and jurisdiction. A common starting point is law and approved safety controls, then applicable contractual or industry authority, then current internal policy, then general reference material. Where that hierarchy cannot resolve the conflict, the right behavior is to refuse and escalate rather than silently choose between two legitimate sources.
None of that can be inferred from the documents. Metadata filters, effective-date fields, and version-aware reranking all help enforce a rule, but a rule cannot be invented on the fly by the AI tool. The business defines the precedence and engineering makes it enforceable during retrieval, which is the same division of labor as ownership.
Grounding, and What It Does Not Promise
Good systems attach a source to every answer: the document, as well as the page or section it came from. That makes an answer checkable, which matters for regulated work and for trust generally. It does not guarantee the answer is correct.
A citation can be irrelevant, incomplete, or attached to the wrong passage, and a confident answer with a plausible-looking source is harder to catch than an obviously wrong one: the assistant that cites the 2022 expense policy, correctly and confidently, for a question the current revision answers differently. Grounding makes verification practical, not impossible.
An Inspection Platform Grounded in Approved Procedures
For an audit and inspection platform, we built a multimodal system grounded in the client’s approved standards and operating procedures. Field teams ask by text, image or voice. Assessment summaries are generated from completed inspections, and findings link back to the source material rather than relying on general model output.
A Licensing Assistant Where the Agreement Changes the Answer
We also run a knowledge assistant in production for a brand licensing business, sitting on years of operational knowledge. Brand guidelines, category rules, territory restrictions, and the accumulated interpretation of a rights framework with an enormous number of valid combinations. Staff and partners ask in plain language, and every answer references its source.
Citations are not a nicety in that environment. An answer about what a licensee may put on a product is a commercial commitment, and the person receiving it needs to see where it came from before acting. The assistant is also reachable from inside other AI tools through Model Context Protocol, so the knowledge is not trapped in one window people have to remember to open.
The hard half there was never retrieval; it was permissions. Two licensees can ask a word-for-word identical question and get different answers because their agreements differ. That is the fourth question: whether it’s a commercial requirement or a security one.
The Trade-Offs You Will Have to Decide
These are business decisions with technical expressions, not the reverse.
Precision against recall. Precision returns fewer, more accurate results. Recall surfaces more, but admits noise. A compliance tool needs precision, because a loose answer is a regulatory exposure. A general knowledge tool can carry more recall. Setting one dial for both user groups is how systems disappoint two audiences at once.
Speed against retrieval quality. Layered ranking usually improves relevance at some cost in latency. For customer-facing tools, speed is what matters most. For internal decision support, quality gets more weight than speed.
Vector-only against hybrid retrieval. Vector search handles meaning well and can miss exact strings: a part number, a contract reference, a regulatory citation. Combining it with keyword search covers more query types. For enterprise content full of identifiers, that combination is usually the right starting assumption, though it is a design decision to test against your own queries rather than a universal rule.
Automation against human review. Automated ingestion keeps the base current and lets bad content through unnoticed; a superseded procedure dropped into a synced folder is indexed on the next sync and served as current until someone notices. For policy and compliance material, a human checkpoint is not optional.
So far, this article has ignored what RAG actually costs to operate. Treating it as a footnote to a strategy article does it no favors.
Not Every Question Belongs to the Knowledge Base
One decision sits above all the tradeoffs above, and getting it wrong can be expensive. Let’s detail it out:
- Documents describe what should happen.
- Systems of record hold what is currently true.
- Route live operational questions to the system that owns the state. Stock, order status, balances, ticket progress, and entitlement checks all belong there.
- The model can interpret the request and explain the result, but the value itself should come through a governed API call to the source of record. The same applies to exact arithmetic, which deterministic code does perfectly and language models do approximately.
Retrieval can reach structured data. The failure is using a periodically indexed document corpus as the source of live state, which is how a system ends up confidently quoting last quarter’s stock position with a citation attached.
An Evaluation Set Is Mostly Failure Cases
Everything above is a claim about what the system should do. Evaluation is how you find out whether it actually does what it should do. Evaluation is critical, which is why it is a standing part of our data and AI engineering engagements. Build your evaluation from real questions the content can answer; questions restricted by role, asked by someone without the role; questions whose best match is a superseded source; questions the content cannot support at all; questions that need live system data.
With these questions formulated, you then need to measure the right things: whether the system retrieved the right evidence and excluded unauthorized content; whether the citations actually support the claims made; whether the system refused when it should have. After launch, watch freshness lag, latency, and cost. Re-run the set whenever a source, a model, or an access rule changes because all three move independently, and any of them can break the others.
A system that passes only the questions it can answer is still a demo. The failure cases are the test.
Knowledge Ownership Is the Difference That Lasts
As models converge, the difference between companies that succeed with AI and those that do not isn’t which AI tool they picked; it is whether the AI can reach the knowledge that makes the answer company-specific, and whether anyone is accountable for that knowledge staying true.
Most commerce and operations teams still treat internal documentation as a records problem rather than an operational asset, which is why so much of it is stale in ways nobody has measured. That is the gap worth closing.
Without an owner for content quality, the system begins degrading the day it goes live.
FAQs
Context. A generic assistant knows a great deal about the world and nothing about your refund policy or your escalation process. RAG connects a language model to your own approved content, so answers come from your material, with the source attached.
No. Retraining alters the model itself and is a far larger undertaking. RAG leaves the model alone and connects it to your content when a question is asked.
Usually, you should not serve both from one retrieval configuration. Compliance work needs high precision because a loose answer is a regulatory problem. General knowledge tools tolerate more recall. Use separate configurations, or metadata filtering that scopes retrieval by query context.
Measure retrieval and answer quality separately. Check whether the retrieved passages were the right ones, and whether citations support every material claim. Test refusal on questions the content cannot answer, and confirm unauthorized material was excluded before it reached the model, not just from the final answer. Then watch adoption by workflow, because a team with access that still works the old way does not trust the system.
You will rarely need to create new material. Instead, you will usually need to clean, classify, support permissions, and connect what you already have. How much work that is depends on the state of the content, which is why it gets assessed before anything is connected.
No. Grounding makes an answer easier to check by linking it to the retrieved source, but a citation can still be irrelevant or wrongly attributed. RAG shifts verification from impossible to practical, but that’s not the same as guaranteed.
Within the risk tolerance you set for the source. Any delay leaves a window in which revoked content can still be retrieved. Deletions deserve particular attention, because removing an original document does not by itself prove that everything derived from it has gone too. Document that path and test it with your privacy team.
Why Your Knowledge Base Keeps Failing You
Answer a few questions to get an instant read on whether it's a content problem, a retrieval problem, or a workflow problem, and what it'll take to fix.
SHARE THIS POST
Article written by
Mayank Kukreja
Latest Insights
Stay ahead of the curve with our expert analysis, industry trends, and actionable advice. Our blog offers fresh perspectives on the challenges and opportunities in the tech landscape, helping you make informed decisions and drive innovation within your organization.
