

Executive Summary And Takeaways
Nearly half of AI proofs of concept now make it into production. Far fewer reach wide-scale deployment, and the model is often not the limiting factor.
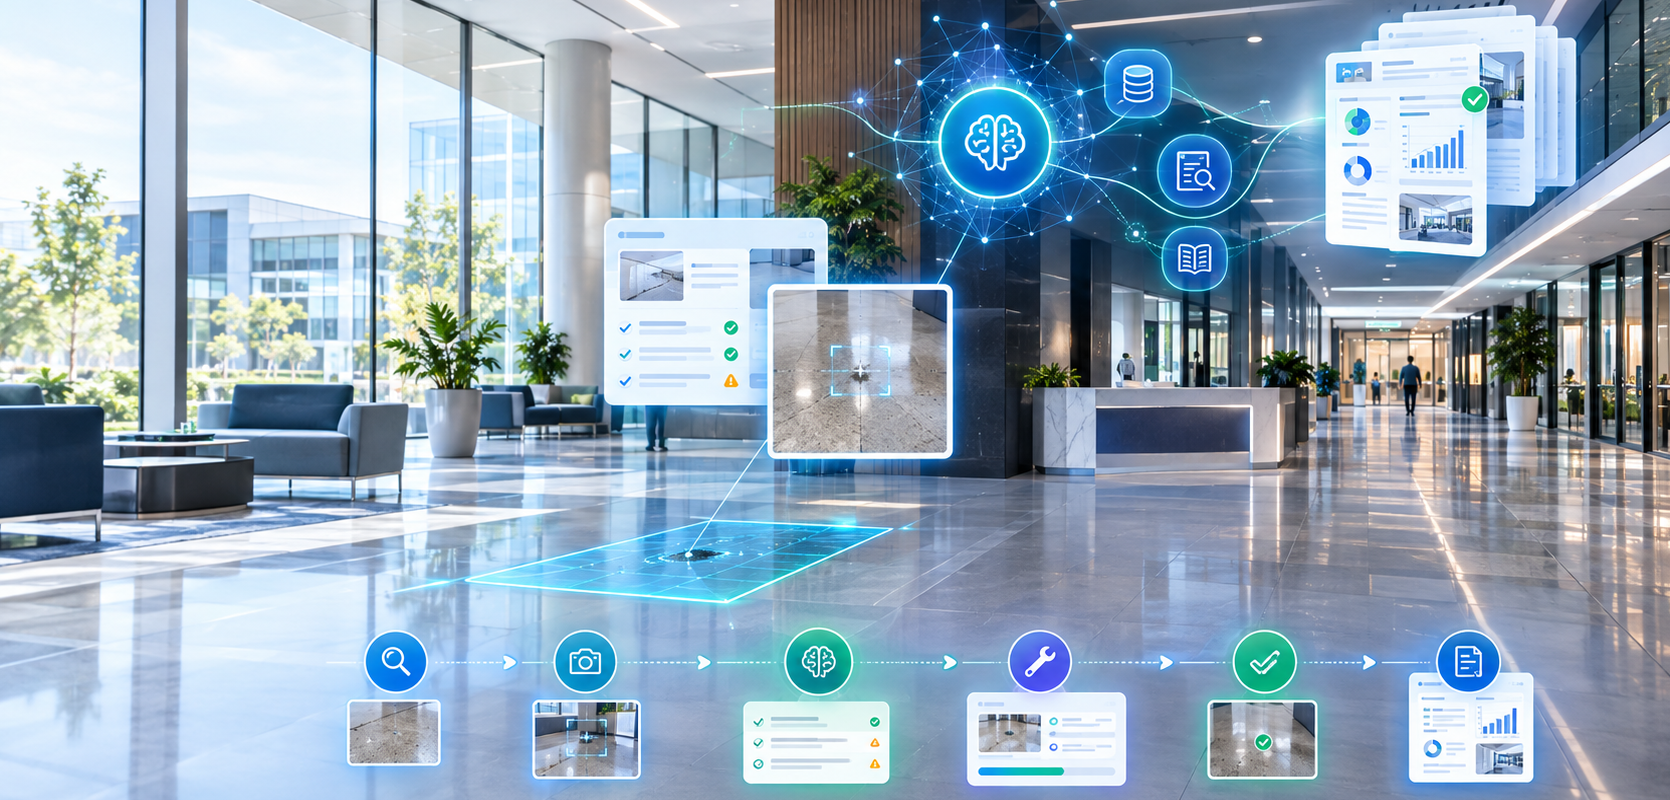
IDC’s research for Lenovo measured different outcomes at different endpoints. RAND interviewed the people who lived it. The pattern is consistent: PoCs and pilots are bounded by design, while production demands evidence that the surrounding workflow, data, architecture, controls, and operating model hold up under sustained real-world use. This article defines the ladder from PoC to scaled value, then gives you five gates to run before production release.
- Production entry is not the same as wide-scale deployment. IDC research for Lenovo found 46 percent of PoCs had entered production in its 2026 study, while its 2025 wave found only four of 33 reaching wide-scale deployment.
- The famous failure statistics measure different things. Deployment, abandonment, and financial impact are separate outcomes, and reading them honestly changes the fix.
- Five gates decide readiness. Value, workflow, data and context, system and control, and operations. Each gate demands evidence, and any gate answered with optimism is the gap.
- High-impact actions never run through the model directly. Deterministic services hold the credentials, apply the policy, and record what happened.
- Run the gate check on your most advanced pilot this week. The weakest gate tells you where the production budget should go first.
The Numbers, Read Honestly
In the CIO Playbook 2026, IDC research for Lenovo found that 46 percent of AI proofs of concept had progressed into production. The 2025 wave of the same research program, as reported by CIO, found that only four of every 33 reached wide-scale deployment, and its authors read that gap as low organizational readiness across data, processes, and infrastructure. The two findings do not contradict each other. Entering production and reaching wide-scale deployment are different endpoints, and the two figures come from separate annual waves with different samples, so they should not be read as one conversion funnel.
That figure usually gets quoted beside others that sound like the same finding. Gartner predicted in July 2024 that at least 30 percent of generative AI projects would be abandoned after proof of concept by the end of 2025, citing poor data quality, inadequate risk controls, escalating costs, and unclear business value. Gartner’s own follow-up analysis put the realized share at 50 percent or more. RAND interviewed 65 experienced practitioners and mapped five recurring root causes of AI project failure. And McKinsey’s State of AI survey examined what separates organizations that see financial impact from those that do not.
These are different gates between experimentation and scaled value, and treating them as one failure rate produces the wrong fix.
| Study | What it measures | The finding |
|---|---|---|
| IDC for Lenovo, CIO Playbook 2026 | Production entry. Did the PoC progress into production? | 46 percent had. |
| IDC for Lenovo, CIO Playbook 2025 | Wide-scale deployment. Did the PoC reach broad use? | Four of every 33 did. |
| Gartner, 2024 prediction and later analysis | Abandonment. Was the generative AI project dropped after PoC? | At least 30 percent predicted; at least 50 percent reported. |
| RAND, 65 practitioner interviews | Causes. Why do projects fail to deliver intended value? | Five recurring root causes; four sit outside the model. |
| McKinsey, State of AI 2025 | Value. What correlates with EBIT impact from generative AI? | Workflow redesign had the biggest effect of 25 attributes tested. |
Read together, these numbers are narrower and more useful than the headlines. Model capability is a genuine limit: RAND names it as one of five causes. But the other four sit outside the model. Leaders misread the problem, the data cannot support the task, teams chase technology instead of outcomes, and the infrastructure was never built for this work.
In plain terms, the model is rarely what stops you. What a proof of concept proves and what production demands are different claims, and the gap between them is where budgets vanish.
One more honest note: not every proof of concept should reach production. Stopping when the economics, the data, or the capability don’t hold is good governance. The failure is funding production against PoC evidence, or letting a viable initiative stall because the surrounding system was never scoped.
Define The Ladder Before You Climb It
Most organizations use PoC, pilot, and production interchangeably, and the vocabulary problem becomes a funding problem. Each stage answers a different question, and each answer is a precondition for the next.
The most common failure sequence starts at approval. A demo built on stage 1 evidence wins a stage 3 budget, and everyone discovers stages 2 and 3 have entry requirements nobody scoped. Engineering gets blamed six months later, but the stall was scheduled the day the committee approved production spend against PoC results.
What this means for your business: before approving any AI budget, name the stage the evidence belongs to and the stage the money is for. If those two labels differ by more than one rung, you are funding a leap, and leaps need the gates below scoped into the plan.
How A Working PoC Becomes A Stalled Initiative
Consider a mid-sized logistics company. Leadership hears competitors talking about AI demand forecasting, and a small team builds a proof of concept on cleaned historical data. Weighted forecast error on the curated history looks excellent in the demo. The steering committee is impressed, and they approve budget for production.
Then the live feeds arrive, and the system meets the data the demo never saw.
Forecast error climbs. The system has to feed its predictions into the ERP and the transport management system through controlled integrations. Still, neither platform was built to handle probabilistic outputs, so integration turns into its own project. Planners keep their spreadsheets, because nobody redesigned their work or gave them a reason to trust the new numbers.
Meanwhile, no one owns the running system. IT doesn’t want it, the business unit never assigned an owner, and the costs of running, monitoring, and reviewing it climb unchecked. Six months of engineering time and an approved budget later, the status line still reads: in evaluation.
The forecasting approach may still be valid, but the live system is failing. Replacing the model would not fix the missing-data handling, the integration path, the planner workflow, the ownership vacuum, or the production controls. Those gaps belong to the surrounding system.
The Five Production Gates
Production readiness is a decision with evidence attached. Before releasing any AI system to production, run all five gates. Value comes first, and the remaining evidence develops in parallel rather than in sequence. Each row states what must exist, not what is planned.
| Gate | Evidence Required Before Proceeding |
|---|---|
| 1. Value | A baseline, a measurable target, an economic case at realistic volume, go-or-kill criteria, and a named business owner with authority. |
| 2. Workflow | A defined place in the real process, redesigned user actions, an adoption plan with training and incentives, exception handling, and human handoffs. |
| 3. Data and context | Representative live data, quality and freshness controls, named ownership and lineage, permissions, and a feedback path from users to the system. |
| 4. System and control | Production integrations, evaluation gates on quality, security and compliance review, deterministic execution of actions, fallbacks, and latency and cost limits. |
| 5. Operations | A named operator, observability across inputs, outputs, and cost, incident response, versioning, service expectations, and an owner for continuous improvement. |
Gate 2 is easy to underweight, and the evidence says it deserves far more scrutiny. Of the 25 organizational attributes McKinsey tested, redesigning workflows had the biggest effect on whether generative AI produced EBIT impact, yet only 21 percent of adopters reported fundamentally redesigning any workflow. In business terms, the single change most tied to financial return is the one most companies skip. Gartner’s abandonment causes span the gates rather than sitting in one: unclear value, poor data, inadequate controls, and unsustainable cost. Gates 4 and 5 are where systems that passed everything else quietly rot, because a system nobody can observe or operate degrades until someone turns it off.
Gate 4 carries one principle that outranks the rest of its row.
The model proposes. Deterministic services authorize, execute, record, and verify.
In plain terms: the AI can recommend an action, but ordinary rule-based software, the kind that behaves the same way every time, is what actually carries it out, logs it, and checks it.
This does not ban AI-driven transactions. It means the model never holds the keys to the systems your business runs on, never skips a policy check, and never writes an unverified change into your records.
Instead, rules route every output based on how confident the system is, what your policies allow, and how costly a mistake would be. Low-risk cases pass straight through. High-risk or unclear cases either stop safely or go to a person, and the amount of human review you add is set by the cost of being wrong.
Notice what is deliberately missing: a single fixed confidence score used as the cutoff. A model’s raw score is not the same as a real probability that it is correct, so a threshold copied from someone else’s blog post is not a safety control.
What Changes By Stack
The five gates are constant. The evidence that satisfies them differs by what you are running, and pretending one checklist covers predictive ML and agentic systems is how teams end up verifying the wrong things.
Predictive ML
- The inputs the model uses are produced the same way every time, kept current, and owned by a named person. (A feature store is one way to do this, not a requirement.)
- The data the model sees in production matches the data it was trained on, so it is judging the same kind of world it learned from.
- After launch, you can still tell whether it is right, because real outcomes flow back in. Without that feedback loop, performance is unmeasurable.
- Someone is watching for the model quietly getting worse over time (this is called drift), with alerts set at a level an operator will actually act on.
- Model versions are tracked, and retraining is controlled: a drift warning starts an investigation, not an automatic swap, and any new version still has to clear the data, quality, and business checks.
Generative And Agentic AI
- You have tested how well answers stay tied to real, approved information (this is grounding), using normal cases, tricky edge cases, and cases built to break it. When the system looks up information before answering, we test that lookup step on its own.
- Before any answer is handed to another system, it is checked to confirm it is in the exact format that system expects, so a malformed output cannot flow downstream.
- Each agent can touch only the specific tools and data it needs, only from a pre-approved list, with checks on what goes in and what comes out.
- Success is judged by the business result the task was meant to produce, not by model scores alone.
- The system handles interruptions, retries, and half-finished tasks on purpose, because a job left half-done is its own kind of failure.
- Actions follow your policies, are verified after they run, and always have a safe route to hand off to a person.
Who Is Accountable For Which Decision
Role descriptions are where accountability blurs. A working ownership model maps decisions to names, with exactly one accountable owner per row. If a row has two accountable owners, it has none.
| Decision | Accountable | Responsible |
|---|---|---|
| Business outcome and baseline | Business sponsor | Product owner |
| Production release | Business sponsor | Engineering lead |
| Data quality and access | Head of data | Data engineering |
| Evaluation gates and quality bar | Engineering lead | ML or platform team |
| Action policy for agents | Product owner | Engineering lead |
| Security and compliance approval | Security or risk owner | Security engineering |
| Incident response | Named operator | Platform team |
| Cost limits and spend alerts | Engineering lead | Platform team |
| Ongoing value measurement | Business sponsor | Product owner |
One row deserves emphasis. Where the system touches regulated data, customer-impacting decisions, or high-impact agent actions, security and compliance hold a mandatory approval gate. Treating them as a courtesy briefing late in the build is a common way projects die a week before launch, with the added cost of having already built everything.
The Decision Gate
Proceed when every gate is answered with evidence. If any answer begins with a plan to figure it out later, the initiative is still a pilot regardless of what the budget line calls it, and the responsible move is to fund the gap rather than the launch.
Organizations that consistently ship AI are not distinguished by better models alone. They treat the move from pilot to production as a discipline that spans the business and the engineering, and they refuse to scale until both sides show green. A proof of concept validates the technique under bounded conditions. What ultimately affects your customers and your P&L is the production system.
FAQs
A proof of concept shows the technique can work, usually on curated data with no integration and no users. A pilot shows it works inside one bounded live workflow with real users and real data. A production system runs at the required scale, reliability, cost, and risk level. Scaled value is the fourth stage: the system is adopted and moving the metric it was funded to move. Many stalled initiatives approved a production budget on PoC evidence and skipped the rungs in between.
IDC research for Lenovo found that 46 percent of AI PoCs had progressed into production in its 2026 study, while its earlier wave found only four of 33 reaching wide-scale deployment. Recurring causes include unclear business value, workflows nobody redesigned, live data that looks nothing like the demo extract, missing controls, and ownership that dissolves after launch. The model itself is often not the limiting factor.
Five gates, each answered with evidence: value, meaning a baseline, target, economic case, and named owner; workflow, meaning a defined place in the real process with an adoption plan; data and context, meaning representative live data with quality controls and lineage; system and control, meaning production integrations, evaluation gates, security review, and deterministic execution; and operations, meaning a named operator with observability, incident response, and cost limits.
The five gates are constant, but the evidence differs. Predictive ML lives or dies on reproducible features, consistent training and serving, drift monitoring, and controlled retraining. Generative and agentic systems depend on grounding quality, structured outputs, scoped tool permissions, task-level evaluation, and policy-controlled actions with post-execution verification. High-impact actions in either stack run through deterministic services rather than directly through the model.
Find Where Your Platform will Block Production
The assessment scores visibility, data foundation, application readiness, and agentic capability, and shows which technical constraints are most likely to stop an AI system from scaling.